• Home
  • About
  • CRAIGBALL.COM
  • Disclaimer
  • Log In

Ball in your Court

~ Musings on e-discovery & forensics.

Ball in your Court

Author Archives: craigball

Leery Lawyer’s Guide to AI

09 Thursday Jan 2025

Posted by craigball in E-Discovery, General Technology Posts

≈ 10 Comments

Tags

ai, artificial-intelligence, chatgpt, eDiscovery, generative-ai, openai, technology

Next month, I’m privileged to be presenting on two topics with United States District Judge Xavier Rodriguez, a dear friend who sits in the Western District of Texas (San Antonio). One of those topics is “Practical Applications for AI.” The longstanding custom for continuing legal education in Texas is that a presenter must offer “high quality written materials” to go with a talk. I’m indebted to this obligation because writing is hard work and without the need to supply original scholarship, I’d probably have produced a fraction of what I’ve published over forty years. A new topic meant a new paper, especially as I was the proponent of the topic in the planning stage–an ask borne of frustration. After two years of AI pushing everything else aside, I was frustrated by the dearth of practical guidance available to trial lawyers–particularly seasoned elders–who want to use AI but fear looking foolish…or worse. So, I took a shot at a practical primer for litigators and am reasonably pleased with the result. Download it here. For some it will be too advanced and for others too basic; but I’m hopeful it hits the sweet spot for many non-technical trial lawyers who don’t want to be left behind.

Despite high-profile instances of lawyers getting into trouble by failing to use LLMs responsibly, there’s a compelling case for using AI in your trial practice now, even if only as a timesaver in document generation and summarization—tasks where AI’s abilities are uncanny and undeniable. But HOW to get started?

The Litigation Section of the State Bar of Texas devoted the Winter 2024 issue of The Advocate magazine to Artificial Intelligence.  Every article was well-written and well-informed—several penned by close friends—but no article, not one, was practical in the sense of helping lawyers use AI in their work. That struck me as an unmet need.

As I looked around, I found no articles geared to guiding trial lawyers who want to use LLMs safely and strategically. I wanted to call the article “The Leery Lawyer’s Guide to AI,” but I knew it would be insufficiently comprehensive. Instead, I’ve sought to help readers get started by highlighting important considerations and illustrating a few applications that they can try now with minimal skill, anxiety or expense. LLMs won’t replace professional judgment, but they can frame issues, suggest language, and break down complex doctrines into plain English explanations. In truth, they can do just about anything that a mastery of facts and language can achieve.

But Know This…

LLMs are unlike any tech tool you’ve used before. Most of the digital technology in our lives is characterized by consistency: you put the same things in, and other things come out in a rigid and replicable fashion. Not so with LLMs. Ask ChatGPT the same question multiple times, and you’ll get a somewhat different answer each time. That takes getting used to. 

Additionally, there’s no single “right” way to interrogate ChatGPT to be assured of an optimal result. That is, there is no strict programming language or set of keywords calculated to achieve a goal. There are a myriad number of ways to successfully elicit information from ChatGPT, and in stark contrast to the inflexible and unforgiving tech tools of the past, the easiest way to get the results you want is to interact with ChatGPT in a natural, conversational fashion.

Continue reading →
Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Safety First: A Fun Day at the “Office”

16 Monday Dec 2024

Posted by craigball in Computer Forensics, E-Discovery, General Technology Posts, Personal

≈ 4 Comments

Tags

bosiet, caebs, drill-ship, forensics, offshore, vdr, voyage-data-recorder

As a forensic examiner, I’ve gathered data in locales ranging from vast, freezing data centers to the world’s largest classic car collection. Yet, wherever work has taken me, I’ve not needed special equipment or certifications beyond my forensic skills and tools.  That is, until I was engaged to inspect and acquire a Voyage Data Recorder aboard a drilling vessel operating in the Gulf of Mexico.

A Voyage Data Recorder (VDR) is the marine counterpart of the Black Box event recorder in an airliner.  It’s a computer like any other, but hardened and specialized.  Components are designed to survive a catastrophic event and tell the story of what transpired.

Going offshore by helicopter to a rig or vessel demands more than a willingness to go.  The vessel operator required that I have a BOSIET with CAEBS certification to come aboard.  That stands for Basic Offshore Safety Induction Emergency Training with Compressed Air Emergency Breathing System.  It’s sixteen hours of training, half online and half onsite and hands on.  I suppose I was expected to balk, but I completed the course in Houston on Thursday.  Now, I’m the only BOSIET with CAEBS-certified lawyer forensic examiner I know (for all the good that’s likely to do me beyond this one engagement).  Still, it was a blast to train in a different discipline.

A BOSIET with CAEBS certification encompasses four units:

  1. Safety Induction
  2. Helicopter Safety and Escape Training (with CA-EBS) using a Modular Egress Training Simulator (METS)
  3. Sea Survival including Evacuation, TEMSPC, and Emergency First Aid
  4. Firefighting and Self Rescue Techniques
Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

“There’s No Better Rule”

28 Wednesday Aug 2024

Posted by craigball in E-Discovery

≈ 9 Comments

“Take nothing on its looks; take everything on evidence. There’s no better rule.”  I quote this line from Charles Dickens’ Great Expectations at the end of all my emails.  It’s my guiding light.  Sure, how things look matters, but how things truly are matters more.  At least it should be that way. 

I reflect on all this while listening to a webinar presented by my friends, Doug Austin and Kelly Twigger, and moderated by Brett Burney.  They discussed so-called Modern Attachments or, as they prefer to call them, Hyperlinked Files.  In a nutshell, Modern Attachments (as Microsoft calls them) are files that are stored in the Cloud and accessed by links transmitted within an email as distinguished from documents embedded within the transmitting e-mail and thus traveling with the e-mail rather than being retrieved by the recipient clicking on a hyperlink.  The debate about the extent of the duty to preserve, collect and produce these modern attachments rages on, and I don’t post here to rehash that back-and-forth.  My purpose is to tackle some misinformation advanced as a basis to exclude modern attachments from the reach of discovery.

Many who paint dealing with Modern Attachments as infeasible or fraught with risk posit that Modern Attachments tend to be collaborative documents or documents that have gone through edits after transmittal.  They argue that they shouldn’t have to produce Modern Attachments due to uncertainty over whether the document collected during discovery differs significantly from how it existed at the time of transmittal. I don’t think that a good argument against collection and review, but once more, not my point here.

My point is that we need to stop asserting that these Modern Attachments are routinely altered after transmittal without evidence of the incidence of alteration.  We should never guess at what we can readily measure.

Based on my experience, most modern attachments (e.g., 85-95%) are not altered after transmittal. Nevertheless, my personal observations mean little in the face of solid data revealing the percentage of Modern Attachments altered after transmittal.  We can measure this.  The last modified dates of Modern Attachments can be compared to their transmittal dates, either en masse or through appropriate sampling.  This will allow us to know the incidence of post-transmittal alteration based on hard evidence rather than assumptions or intuition.  I expect the incidence will vary between disciplines and corporate cultures, but that, too, is worth measuring.

Why hasn’t this been done?  A suspicious mind would conclude that those holding the data–who also happen to be the ones resisting the obligation to produce Modern Attachments–don’t want to know the metrics. Less archly, maybe they simply haven’t taken the time to measure, as guessing is easier. As they say in The Man Who Shot Liberty Valance, “This is the West, sir. When the legend becomes fact, print the legend.”  Facts are inconvenient. They’re sticking with the legend.

But it’s time to quit that.  It’s time to take everything on evidence.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Adapting Requests for Production for AI GLLM Assessment

19 Monday Aug 2024

Posted by craigball in Uncategorized

≈ 6 Comments

The integration of Generative Large Language Models (GLLMs) into the discovery process is transforming how documents are reviewed for relevance and responsiveness. These AI models, which excel at processing large document collections, offer significant efficiency improvements. However, to harness their full potential, requests for production (RFPs) must evolve to reflect the unique capabilities and limitations of AI systems. Traditional language in RFPs, which relies heavily on human intuition, needs to be adjusted to accommodate AI’s reliance on clear instructions, context, and precision. This post explores how to adapt requests for production to optimize GLLM usage, addressing both business disputes and tort claims. I’ll provide examples to illustrate how common RFPs can be refined for AI-assisted document review.

Effective AI Prompts in Discovery

AI systems like GLLMs function best with well-structured prompts. In the context of discovery, this means adjusting RFPs to emphasize clarity, specificity, and relevance. The key elements for constructing effective AI prompts in legal discovery are:

  1. Clarity and Specificity: Ambiguity can cause AI systems to miss important documents or misclassify irrelevant ones. Specific requests guide the AI more effectively.
  2. Contextual Guidance: AI relies on context to assess relevance. Providing additional background or specifying the purpose of certain requests helps refine the search.
  3. Keyword Precision: GLLMs rely on keywords to understand and evaluate document content. Choosing precise terms helps reduce the retrieval of irrelevant documents.
  4. Examples: AI systems can better identify relevant documents if examples are provided within the RFP, as they offer patterns for the system to follow.

Incorporating these principles into RFPs ensures that AI models can make the most accurate assessments during document review.

Adapting Requests for Production: Business Dispute and Tort Claim Examples

Both business disputes and tort claims involve unique types of documents and keywords. Adapting RFPs to suit GLLM’s capabilities involves providing detailed instructions for both.

Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

AI Drawing Programs: ChatGPT Versus PlaygroundAI

12 Monday Aug 2024

Posted by craigball in General Technology Posts

≈ 3 Comments

Of late, I’ve come to use AI generated imagery in lieu of my own work or open-source and licensed works as a source for digital storytelling.  My friend, blogger Doug Austin (perhaps the hardest working man in e-discovery) has been illustrating his daily blog posts with AI-generated art for quite some time and I kid him now-and-then about the abundance of robots in his illustrations.  I feel besieged by robot imagery.

Last week in San Antonio, I co-presented on AI evidence at a huge annual conclave of family law practitioners.  I’ve been using ChatGPT, Dall-E and Midjourney for image generation, but preparing the new presentation, I kicked the tires of several tools I’d not used before.  One of them impressed me so I thought I’d post to share it.  I think it blows the doors off ChatGPT’s images.  It’s called PlaygroundAI  It lets users create up to 50 images per day at no charge, and up to 1,000 images a day on its Pro plan ($15/month paid monthly, cancel any time).

Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Doveryai, No Proveryai!

07 Wednesday Aug 2024

Posted by craigball in Computer Forensics, E-Discovery, General Technology Posts

≈ 4 Comments

I recently published an AI prompt to run against search terms then get the AI to propose improvements.  Among the pitfalls I’d hoped to expose was the presence of “stop” or “noise” words; terms routinely excluded from search indices.  Searches incorporating stop words fail because terms not in the index won’t be found.  Ensuring your searches don’t include stop words is an essential step in framing effective queries.

To help the AI recognize stop words, the prompt included a list of default stop words for well-known eDiscovery tools.  That is, I thought I’d done that, but what I included in error (and have now replaced) was ChatGPT’s rendition of stop words for the major tools.  I’d made a mental note to check the lists supplied but—DOH!—I plugged it into the prompt and then forgot to do my due diligence.

I was feeling pretty good about the post and getting some nice feedback.  Last night, my dear friend and e-discovery Empress Mary Mack commented on the novelty of seeing the various stop word lists broken out in a ready reference.  I think echoes of Mary’s kind comment woke me at 4:00am, my subconscious screaming, “HEY DUMMY!  Did you verify those stop words?  Tell me you didn’t blindly trust an AI?!?”

So, long before sunrise, I was manually checking each stop word list against product websites and—lo and behold—every list was off: some merely incomplete but others not even close. ChatGPT hallucinated the lists, and I failed to do the crucial thing lawyers must do when using AI as a research assistant: Trust but verify.

No harm done, but I share my chagrin here to underscore that you just cannot trust an AI generative large language model to do your research without careful human assessment of the output.  I know this and let it slip my mind.  Last time for that.  I’ve corrected the prompt on my blog and hope I’ve gotten it right.  I post this to remind my readers that AI LLMs are great—USE THEM–but they are no substitute for you.  Doveryai, no proveryai!

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

AI Prompt to Improve Keyword Search

04 Sunday Aug 2024

Posted by craigball in Computer Forensics, E-Discovery, General Technology Posts

≈ 15 Comments

Twenty years ago, I dreamed up a website where you would submit a list of eDiscovery keywords and queries and the site would critique the searches and suggest improvements to make them more efficient and effective. It would flag stop words, propose alternate spellings, and alert the user to pitfalls making searches less effective or noisy. I even envisioned it testing queries against a benign dataset to identify overly broad terms and false hits.

I believed this tool would be invaluable for helping lawyers enhance their search skills and achieve greater efficiency. Over the years, I tried to bring this idea to life, seeking proposals from offshore developers and pitching it to e-discovery software publishers as a value-add. In the end, a pipe dream. Even now, nothing like it exists.

The emergence of AI-powered Large Language Models like ChatGPT made me think what I’d hoped to bring to life years ago might finally be feasible. I wondered if I could create a prompt for ChatGPT that would achieve much of what I envisioned. So, I dedicated a sunny Sunday morning to playing “prompt engineer,” a whole cloth term for those who craft AI prompts to achieve desired outcomes.

The result was promising, a significant step forward for lawyers who struggle with search queries without understanding why some fail. Most search errors I encounter aren’t subtle. I’ve written about ways to improve lexical search, and the techniques aren’t rocket science, though they require some familiarity with how electronically stored information is indexed and how search syntaxes differ across platforms. Okay, maybe a little rocket science. But if you’re using a tool for critical tasks, shouldn’t you know what it can and cannot do?

Some believe refining keywords and queries is a waste of time, casting keyword search as obsolete. Perhaps on your planet, Klaatu, but here on Earth, lawyers continue using keywords with reckless abandon. I’m not defending that but neither will I ignore lawyers’ penchant for lexical search. Until the cost, reliability, and replicability of AI-enabled discovery improve, keywords will remain a tool for sifting through large datasets. However, we can use AI LLMs right now to enhance the performance and efficiency of shopworn approaches.

Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Yes, AI is Here. No, You’re Not Gone.

01 Thursday Aug 2024

Posted by craigball in E-Discovery, General Technology Posts

≈ 6 Comments

Yesterday, I sought to defend the value of my law school course on E-Discovery & Digital Evidence to a law Dean who readily conceded that she didn’t know what e-discovery was or why it would be an important thing for lawyers to understand.  It was a bracing experience.

My métier has always been litigation, to the point that everyone I work with sits in and around trial practice.  My close colleagues recognize that 90% of what trial lawyers do is geared to discovery and motion practice, and much of that motion practice is prompted by discovery disputes. So, hearing how a tax lawyer and academic viewed litigation was eye-opening, and troubling to the extent it impacts what’s taught to new lawyers.

Do you agree about the centrality of discovery to litigation, Dear Reader?

The Dean shared her sense that discovery is being replaced by AI and that “soon AI will handle the production of relevant information instead of lawyers.”  I replied that I expected the review phase to be abetted or supplanted by AI in the near term—that’s here—but it would be some time before all the tasks that come before review would be fully AI-enabled.

The idea that there are crucial tasks requiring lawyer intervention before review was surprising to her.  For those who don’t manage electronic discovery day-to-day, electronically stored information seems to magically appear in review tools.  But for e-discovery folks, the march through identification, preservation, collection and processing is our path, and we know that no one, and no AI, can undertake an assessment of the evidence without facing the data.

You’ve got to face the evidence to assess the evidence.

That’s axiomatic; but it’s downplayed by those shouting “AI! AI!”  As they say in these parts, “you’ve got to put the hay down where the goats can get it.”  Until AI is embedded in everything, until AI faces the data in every phone, cloud repository, storage medium and database in ways that support discovery, the goats can’t get to the hay.

The evidence in our cases is not a “collection” until it’s collected.  That doesn’t necessarily mean a copy must be made to isolate data of interest, but that remains the prevailing way that a discrete assemblage of potentially responsive ESI is marshaled before it is processed for search and review.  Not until that occurs does the evidence face human or AI review.

Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Garden Variety: Byte Fed. v. Lux Vending

12 Wednesday Jun 2024

Posted by craigball in E-Discovery

≈ 9 Comments

Tags

ESI Protocols, search

My esteemed colleagues, Kelly Twigger and Doug Austin, each posted about a recent discovery decision from the Middle District of Florida, case no. 8:23-cv-102-MSS-SPF, styled, Byte Fed., Inc. v. Lux Vending LLC. and decided by United States Magistrate Judge Sean Flynn on May 1, 2024.

Kelly and Doug share their customarily first-rate analyses of the ruling insofar as its finding that the assertion of boilerplate objections serves as a waiver.  The Court spanked defendant, The Cardamone Consulting Group, LLC, for its conduct.  That’s been picked apart elsewhere, and I have nothing to add.  I write here to address a feature of the dispute that no one has discussed (and sadly, neither did the Court), being the nature of the request for production that prompted the boilerplate objection of “vague and incomprehensible.”  We can learn much more from the case than just boilerplate=waiver.

Let’s look at the underlying request:

DOCUMENT REQUEST NO. 7:

All documents and electronically stored information that are generated in applying the search terms below to Your corporate email accounts (including but not limited to the email accounts for Nicholas Cardamone, Daniel Cardamone, and Patrick McCloskey):

ByteBitcoin w/s FloridaStanton
ByteFederalBitcoin w/s trademarkBranden w/3 Tawil
Byte FederallawsuitBrandon w/3 Mintz
most w/5 trustedScott w/3 BuchananDKI
Google w/s trademarkconfusion or confusedDynamic w/5 keyword

In its Motion to Compel, Plaintiff calls this request “clear on its face, and … a garden-variety type of request for production in connection with narrowly tailored search terms.”  The Plaintiff adds, “[y]et during the parties’ meet-and-confer, and although Cardamone’s counsel claimed that she was familiar with electronic discovery, the assertion was that her client – a company that has purportedly generated hundreds of millions of dollars in connection with online advertising and electronic data – ‘did not understand what to do.’”

So, Dear Reader, would you understand what to do? You’re steeped in electronic discovery—that’s why you’ve stopped by—but is the request clear, narrowly tailored and “garden-variety” such that we can apply it to a proper production workflow?  A few points to ponder:

1. There’s nothing in the Federal Rules of Civil Procedure that prohibits a request to run specific queries against databases, and email accounts are databases.  Rule 34 requires only that the request “describe with reasonable particularity each item or category of items to be inspected.” 

Conventional requests are couched in language geared to relevance; that is, the requests seek documents and ESI about a topic.  Counsel must then apply the law and the facts to guide clients in identifying responsive information.  Counsel reviews the information gathered and decides whether it’s responsive or should be withheld as a matter of right or privilege.

Over time, the notion took hold that sifting through electronically stored information was unduly burdensome, so opposing parties were expected to work together to fashion queries–“search terms” –to narrow the scope of review.  These keyword negotiations run the gamut from laughable to laudable. They’re duels between counsel frequently unarmed with knowledge of the search tools and processes or of the data under scrutiny.  In short, they use their ginormous lawyer brains to guess what might work if the digital world were as they imagine it to be.

Here, the plaintiff cuts to the chase, eschewing a request couched in relevance in favor of asking that specific searches be run: half of them Boolean constructs employing two types of proximity connectors. 

Was this smart?   You decide.

Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Girding for the E-Savvy Opponent (Revisited)

26 Friday Apr 2024

Posted by craigball in Computer Forensics, E-Discovery, Uncategorized

≈ 7 Comments

Tags

competence, disclosure, discovery, edisclosure, eDiscovery

A friend shared that she was seeing the Carole King musical, “Beautiful,” and I recalled the time I caught it twice on different visits to London in 2015 because I enjoyed it so. I reflected on why I was in London in Summer nine years ago and came across a post from the time–a post that I liked well-enough to revisit it below. I predicted the emergence of the e-savvy opponent, something that has indeed come to pass, yet less-widely or -effectively than I’d hoped (and still hope for). A new generation of e-discoverers has emerged since, so perhaps the post will be fresh (and remain relevant) for more than a few, and sufficiently forgotten to feel fresh for the rest:

(From May 12, 2015): I am in Great Britain this week addressing an E-Discovery and Information Governance conclave, joined by esteemed American colleagues and friends, Jason Baron and Ralph Losey among other luminaries.  My keynote topic opening the conference is Girding for the E-Savvy Opponent. Here is a smattering of what I expect to say.

I arrived in London from Budapest in time to catch some of the events for the 70th anniversary of VE Day, marking the hard-won victory over Germany in the war that shortly followed the war that was to have ended all wars.

As we sported poppies and stood solemnly at the Cenotaph recalling the sacrifices made by our parents and grandparents, I mulled technology’s role in battle, and the disasters that come from being unprepared for a tech-savvy opponent.

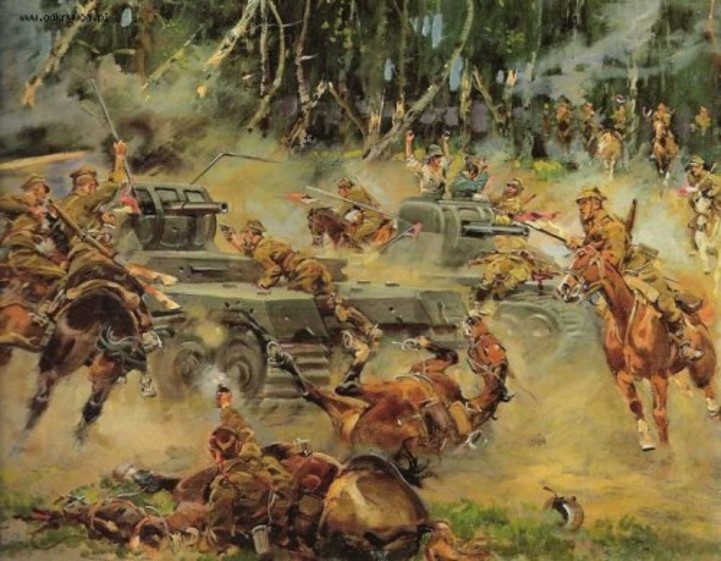
It’s said that, “Generals are always prepared to fight the last war.” This speaks as much to technology as to tactics.  Mounted cavalry proved no match for armored tanks.  Machine guns made trench warfare obsolete.  The Maginot Line became a punch line thanks to the Blitzkrieg. “Heavy fortifications?  “No problem, mein schatzi, ve vill just drive arount tem.”

In e-disclosure, we still fight the last war, smug in the belief that our opponents will never be e-savvy enough to defeat us.

Our old war ways have served so long that we are slow to recognize a growing vulnerability.  To date, our opponents have proved unsophisticated, uncreative and un-tenacious.  Oh, they make a feint against databases here and a half-hearted effort to get native production there; but, for the most part, they’re still fighting with hordes, horses and sabers.  We run roughshod over them.  We pacify them with offal and scraps.

But, we don’t think of it that way, of course.  We think we are great at all this stuff, and that the way we do things is the way it’s supposed to be done.  Large companies and big law firms have been getting away with abusive practices in e-disclosure for so long that they have come to view it as a birthright.  I am the 19th Earl of TIFF.  My father was the Royal Exchequer of Keywords.  I have more than once heard an opponent defend costly, cumbersome procedures that produce what I didn’t seek and didn’t want with the irrefutable justification of, “we did what we always do.”

Tech-challenged opponents make it easy.  They don’t appreciate how our arsenal of information has changed; so, they shoot at us with obsolete requests from the last war, the paper war.  They don’t grasp that the information they need now lives in databases and won’t be found by keywords.  They demand documents.  We have data.  They demand files.  We have sources.

Girding for the Tech Savvy Opponent-IQPC 2015

But, our once tech challenged opponents will someday evolve into Juris Doctor Electronicus.  When they do, here is some of what to expect from them:

E-savvy counsel succeeds not by overreaching but by insisting on mere competence—competent scope, competent processes and competent forms of production.  Good, not just good enough.

Your most effective defense against e-savvy counsel is the Luddite judge who applies the standards of his or her former law practice to modern evidence. Your best strategy here is to continue to expose young lawyers to outmoded practices so that when they someday take the bench they will also know no better way.

Another strategy against e-savvy counsel is to embed outmoded practices in the rules and to immunize incompetence against sanctions.

But these are stopgap strategies–mere delaying tactics.  In the final analysis, the e-savvy opponent needn’t fear retrograde efforts to limit electronic disclosure. Today, virtually all evidence is born electronically; consequently, senseless restrictions on electronic disclosure cannot endure unless we are content to live in a society where justice abides in purposeful ignorance of the evidence.  We have not fallen so, and we will not fall that far.

The e-savvy opponent’s most powerful ally is the jurist who can distinguish between the high cost and burden occasioned by poor information governance and the high cost and burden that flows from overreaching by incompetent requests.  Confronted with a reasonable request, this able judge will give you no quarter because your IG house is not in order.

E-savvy counsel well understands that claims like, “that’s gone,” “we can’t produce it that way” and “we searched thoroughly” rarely survive scrutiny.

It’s not that no enterprise can match the skills of the e-savvy opponent. It’s that so few have ever had to do so.  Counsel for producing parties haven’t had to be particularly e-savvy because opposing counsel rarely were.

Sure, you may have been involved in the Black Swan discovery effort–the catastrophic case where a regulator or judges compelled you to go far beyond your normal scope. But, is that sustainable? Could you do that on a regular basis if all of your opponents were e-savvy?

You may respond, “But we shouldn’t have to respond that way on a regular basis.” In fact, you should, because “e-savvy” in our opponents is something we must come to expect and because, if the opponent is truly e-savvy, their requests will likely smack of relevance and reasonableness.

Remember, the e-savvy opponent about which I warn is not the twit with a form or the wanker who’s simply trying to inflate the scope of the disclosure as a means to extort settlement.  They’re no match for you.  The e-savvy opponent to fear is the one who can persuade a court that the scope is appropriate and proportionate because it is, in fact, both.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...
← Older posts
Newer posts →
Follow Ball in your Court on WordPress.com

Enter your email address to subscribe to this blog and receive notifications of new posts by email.

Join 2,240 other subscribers

Recent Posts

  • A Little Grace November 3, 2026
  • Stolen Valor, Esquire October 31, 2026
  • Fifteen Years in Your Court August 21, 2026
  • The AI Protective Order Double Standard July 27, 2026
  • Drafting RFPs for Robots to Read July 20, 2026

Archives

RSS Feed RSS - Posts

CRAIGBALL.COM

Categories

EDD Blogroll

  • Sedona Conference
  • The Relativity Blog
  • eDiscovery Today (Doug Austin)
  • E-D Team (Ralph Losey)
  • GLTC (Tom O'Connor)
  • CS DISCO Blog
  • Minerva 26 (Kelly Twigger)
  • Basics of E-Discovery (Exterro)
  • Corporate E-Discovery Blog (Zapproved )
  • Illuminating eDiscovery (Lighthouse)
  • Complex Discovery (Rob Robinson)
  • E-Discovery Law Alert (Gibbons)
  • eDiscovery Journal (Greg Buckles)

Admin

  • Create account
  • Log in
  • Entries feed
  • Comments feed
  • WordPress.com

Enter your email address to follow Ball in Your Court and receive notifications of new posts by email.

Website Powered by WordPress.com.

  • Subscribe Subscribed
    Ball in your Court
    Join 2,092 other subscribers

    Have a WordPress.com account? Log in now.

  • Ball in your Court
    View site in Reader
    Manage subscriptionsSign upLog in
    Report this content
    Collapse this bar
Loading Comments...
%d