• Home
  • About
  • CRAIGBALL.COM
  • Disclaimer
  • Log In

Ball in your Court

~ Musings on e-discovery & forensics.

Ball in your Court

Category Archives: E-Discovery

A Guide to Forms of Production

19 Monday May 2014

Posted by craigball in Computer Forensics, E-Discovery, Uncategorized

≈ 6 Comments

forms_iconSemiannually, I compile a primer on some key aspect of electronic discovery.  In the past, I’ve written on computer forensics, backup systems, metadata and databases. For 2014, I’ve completed the first draft of the Lawyers’ Guide to Forms of Production, intended to serve as a primer on making sensible and cost-effective specifications for production of electronically stored information.  It’s the culmination and re-purposing of much that I’ve written on forms heretofore, along with new material extolling the advantages of native and near-native forms.

Reviewing the latest draft, there is much I want to add and re-organize; accordingly, it will be a work-in-progress for months to come.  Consider it a “public comment” version.  The linked document includes exemplar verbiage for requests and model protocols for your adaption and adoption.  I plan to add more forms and examples. Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Pilcrow and Thorn. That 70’s Cop Show, Right?

12 Monday May 2014

Posted by craigball in E-Discovery

≈ 2 Comments

I’ve lately been immersed in the minutiae of load files while trying to complete a primer on forms of production and craft a load file exercise for the workbook students will use in the upcoming Georgetown E-Discovery Training Academy.

By the way, there’s still time to register for the ultimate e-discovery master class cum boot camp—a week in Washington, D.C. studying electronic discovery with a dedicated faculty, getting down and dirty with data.  You promised you were going to get your arms around the e-stuff; now is the time, and the Georgetown Academy is the place.  June 1-6, 2014.  I’ll sweeten the pot: Use the code EDTAREFERRAL when registering and take $300.00 off the price.

While sojourning in load file hell, I stumbled upon a tidbit of information I thought other e-discovery groupies might find mildly diverting.

Our Sesame Street words for today are Thorn and Pilcrow.

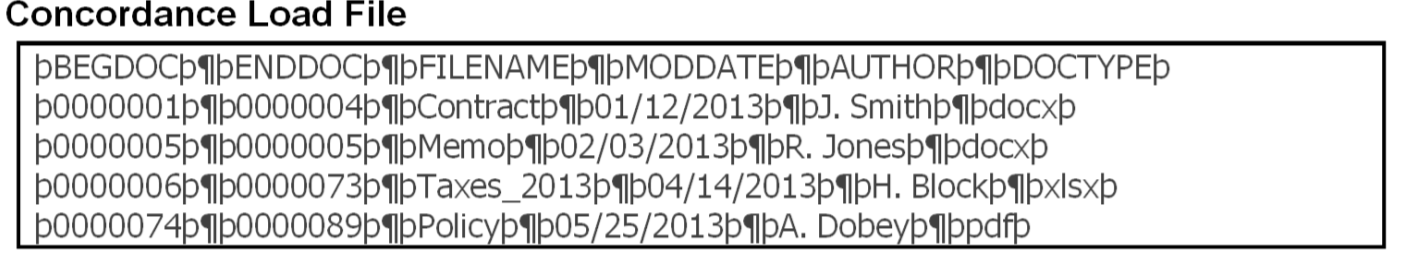
I refer, of course to the two symbols that serve as familiar field delimiters in Concordance load files; those persnickety text files that carry metadata and other information into e-discovery review tools.  In order for tabular data to be discretely searchable, it has to be set off (“fielded”) from other data by a separator.  On paper, we do this with vertical and horizontal lines, drawing rows and columns.  We literally delineate the fields of data so first names don’t wander into, say, last names or street names.  To accomplish the same end with digital data in load files, we use delimiters, such as commas, tabs or, in the case of Concordance load files, thorns and pilcrows.

A Thorn looks like this: þ and a Pilcrow looks like this: 
When seen in a load file, they look like this:

load file

If you’re like me, you’ve been happily calling pilcrows “paragraph symbols” for quite some time, and had no idea that very pregnant capital “I” was called a thorn.

But here’s the cool part: Thorns were very nearly a part of our modern English alphabet.  No kidding.  Apart from our boundless delight communing with thorns in load files, we nearly see a thorn every time we come across some cheesy shop that calls itself “Ye Olde This or That.”  The thorn was once a character standing in for the letter combination “TH” and pronounced the same way.   So, many signs in jolly ol’ England once read “þe” pronounced “the.”

Over time, what with old English scripts and fading paint and such, the thorn morphed into the letter “Y” and all those “þe Olde Curiosity Shoppes” became “Ye Olde Curiosity Shoppes.”  Another explanation is that, with the advent of the printing press, countries like Germany and Italy who exported typefaces didn’t use the thorn in their languages; so, they didn’t make thorn type.  Accordingly, those who thought the letter Y served as a reasonable facsimile started using it in lieu of the thorn.

When you see a thorn in a load file, smile.  We very nearly lost her forever.

Hat tip to http://mentalfloss.com/article/31904/12-letters-didnt-make-alphabet

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Broken Badly: The Anderson Living Trust v. WPX Energy Production

08 Thursday May 2014

Posted by craigball in E-Discovery

≈ 3 Comments

Breaking BrowningU.S. District Judge James Browning is a fine fellow.  There are many reasons to say so; but the first is that, though he sits in New Mexico, he was born in the Great State of Texas.  Judge Browning kindly spoke to my E-Discovery class at the law school in September 2012.  I’d sought him out because he’d been ably grappling with e-discovery issues in a case styled S2 v. Micron.  In his remarks to my class, he splendidly recounted some of the challenges faced by judges who ascended to the bench before the Age of Digital Evidence.  Judge Browning has one of those C.V.s that could make any lawyer hate him (e.g., Yale, varsity letterman, Law Review editor-in-chief, Coif, Supreme Court clerk); but he’s a good judge and a nice guy to boot.

I share my admiration of Judge Browning to underscore that I feel a bit of a rat in expressing misgivings about his recent opinion in The Anderson Living Trust v. WPX Energy Production, LLC, No. CIV 12-0040 JB/LFG. (D. New Mexico March 6, 2014).  I think he got it wrong in some respects–not on the peculiar equities of the case before him, but in his broader analysis of Rule 34 of the Federal Rules of Civil Procedure and in conjuring a Hobson’s choice for requesting parties.  Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Amending the Proposed Amendments

15 Saturday Feb 2014

Posted by craigball in E-Discovery

≈ 12 Comments

drawing boardToday was ostensibly the last day for public comment on the proposed amendments to the Federal Rules of Civil Procedure.  The good news for other procrastinators is that the submission deadline has been extended to accommodate scheduled website maintenance,  The new deadline for submitting public comments is 11:59 PM ET on Tuesday, February 18, 2014.  Over 1,600 comments have been submitted, and I’ve been trying to wade through them, unsurprised at the deep division between plaintiffs and corporate interests.  I can’t recall another time when so much has been spent by corporate lobbyists to influence the civil rulemaking process.  Clearly, corporate America expects a bigger payoff from these proposed amendments than I do.

Notwithstanding their strengths, there are aspects of the proposed amendments that should go back to the drawing board.  Many commentators focus on problems with Proposed Rule 26 and it’s efforts to narrow the scope of discovery.  Some are incensed that proposed Rule 37(e) offers insufficient immunity from sanctions for spoliation, choosing to ignore the fact that the incidence of spoliation sanctions in federal court is historically less than the national incidence of death by lightning strike.  Ironically, those grousing the loudest are the same white shoe-types who play golf in a thunderstorm.

I finally threw my comment on the pyre, I mean pile, or, at least I tried to do so; but, the submission web page was indeed shut down for website maintenance.  That gave me time to solicit your input, dear reader, while there’s still a chance to tweak my comments if you find I’ve made a mess of it.  Here’s what I’m planning to submit: Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Query the Quintessential Quintet

20 Monday Jan 2014

Posted by craigball in Computer Forensics, E-Discovery, General Technology Posts

≈ 1 Comment

fab5judges

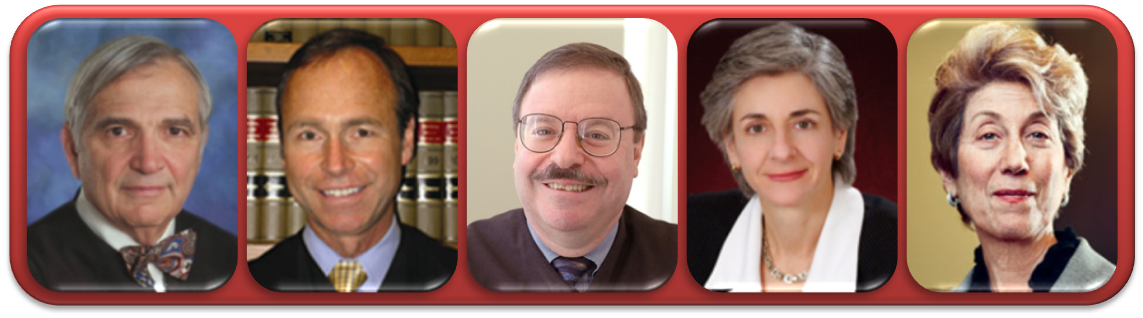
On Wednesday, February 5, 2014 at 9:00am, I’m moderating a plenary session at LegalTech New York where the panelists are a veritable Mount Olympus of e-discovery leaders from the federal bench: John Facciola, James Francis, Andrew Peck, Lee Rosenthal and Shira Scheindlin.  I can hardly imagine a more quintessential quintet of rare knowledge and eloquence!  Kudos to ALM educational coordinator, Judy Kelly, for deftly getting them all to commit.

The judges will be discussing some of what you might expect, e.g., proposed Rules amendments, predictive coding, Rule 502 and expectations of lawyer technical competence.  We will also be exploring a few fresh issues, like the impact all those little screens are having on everyone in and out of court.

There’s still time to add topics and questions of interest to you to the program; so, if you have questions you’d pose or topics you’d explore, please share them here as a comment (or e-mail them to me: craig at ball dot net), and I’ll try to work them in.  Hope to see you in New York!

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Thanks. Can You Do Me a Favor Please?

19 Sunday Jan 2014

Posted by craigball in Computer Forensics, E-Discovery, General Technology Posts, Personal, Uncategorized

≈ 5 Comments

Sorry to take your time asking for help. so I’ll be quick about it.

But first, thank you.  Thanks to you, dear reader, this blog and its 85 posts reached 100,000 views a few days ago.  That’s nothing compared to the millions of page views others see, but it’s very gratifying to me because I launched this blog without saying a word to anyone.  Somehow, you just found it.  Ball in Your Court is an outlet born of frustration with the two-month publication lag attendant to my former print column and the sudden shuttering of an American Lawyer Media blog where I’d previously posted.  I wanted a place where no one could pull the plug but you or me.  This blog is a very personal connection to you.

The favor I ask is this:  if you like the content here or find it of some value, please share it with someone you think might be interested.  If you have a blog or site with a blogroll, please consider adding Ball in Your Court to your blogroll.  I will try to earn my place on your page and in your day.  Thanks.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Forms that Function

16 Thursday Jan 2014

Posted by craigball in E-Discovery

≈ 3 Comments

forms that functionOver the course of the last decade, it’s been a Sisyphean task to get lawyers to lay aside rigid ideas about forms of production in e-discovery and focus on selecting forms that function. 

“Forms that function.”  Forms of production that work.

Ever since the demanding class, “Architecture for Non-Architects” at Rice University, I’ve been a wannabe architect, and the battle cry, “form follows function,” my mantra.  It’s ascribed to Louis Sullivan, legendary American architect and Father of the Skyscraper.  “Form follows function” fairly defines what we think of as “modern,” and it’s a credo at the heart of the clearest idea I’ve had in a while, being that we should produce e-mail in forms that can be made to function in common e-mail client programs like Microsoft Outlook.

I don’t point to Outlook because I think it a suitable review platform for ESI (I don’t, though many use it that way).  I point to Outlook because it’s ubiquitous and, if a message is produced in a form that can be imported into Outlook, it’s a form likely to be searchable, sortable, utile and complete.  More, it’s a form that anyone can assimilate into whatever review platform they wish at lowest cost.

The criterion, “Will the form produced function in an e-mail client?” enables parties to explore a broad range of functional native and near-native forms, not just PSTs.  It an objective “acid test” to determine if e-mail will be produced in a reasonably usable form; that is, a form not too far degraded from the way the data is used by the parties and witnesses in the ordinary course.

Forms that Function retain essential features like Fielded Data, allowing users to reliably sort messages by date, sender, recipients and subject, as well as Message IDs, supporting the threading of messages into coherent conversations.  Forms that Function supply the UTC Offset Data within e-mails that allows messages originating from different time zones and using different Daylight Savings Time settings to be normalized across an accurate timeline. Forms that Function don’t disrupt the Family Relationships between messages and attachments.  Forms that Function are inherently electronically searchable.

Best of all, producing Forms that Function means that all parties receive data in a form that anyone can use in any way they choose, visiting the costs of converting to alternate forms on the parties who want those alternate forms and not saddling parties with forms so degraded that they are functionally fractured and broken.

If you are a requesting party, don’t be bamboozled by an alphabet soup of file extensions when it comes to e-mail production (PST, OST, MSG, EML, DBX, NSF, MHTML, TIFF, PDF, RTF, TXT, DAT, XML).  Instead, tell the other side, “I want Forms that Function.  If it can be imported into Microsoft Outlook and work, that form will be fine by me.”

If the other side says, “We will pull all that information out of the messages and give it to you in a load file,” say, “No thanks, leave it where it lays, and give it to me in a Form that Functions!“
Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Revisiting ‘How Many Documents in a Gigabyte?’

15 Wednesday Jan 2014

Posted by craigball in Computer Forensics, E-Discovery

≈ 6 Comments

equalI once wrote a column titled “Page Equivalency and Other Fables.”  It lambasted lawyers who larded their burden arguments with bogus page equivalencies like, “everyone knows a gigabyte of data equates to a pile of printed pages that would reach from Uranus to Earth.”  We still see wacky page equivalencies, and “from Uranus” still aptly describes their provenance.

Back in 2007, I wrote, “It’s comforting to quantify electronically stored information as some number of pieces of paper or bankers’ boxes.  Paper and lawyers are old friends.  But you can’t reliably equate a volume of data with a number of pages unless you know the composition of the data.  Even then, it’s a leap of faith.”

So, I’m happy to point you to some notable work by my friend, John Tredennick.  I’ve known John since the emerging technology was fire and watched with awe and admiration as John transitioned from old-school trial lawyer to visionary forensic technology entrepreneur running e-discovery service provider, Catalyst.  John is as close to a Renaissance man as anyone I know in e-discovery, and when John speaks, I listen.

Lately, John Tredennick shared some revealing metrics on the Catalyst blog looking at the relationship between data and document volumes, an update to his 2011 article called, How Many Documents in a Gigabyte?  John again examines document volumes seen in the data that Catalyst receives and processes for its customers and, crucially, parses the data by file type.  As the results bear out, the forms of the data still make an enormous difference in terms of data volume.  Even as between documents we think of as being “the same” (like Word .doc and .docx formats), the differences are striking.

For example, John’s data suggests that there are almost 60% more documents in a gigabyte of Word files in the .docx format (7,085) than in a gigabyte of files stored in the predecessor .doc format (4,472).  This makes sense because the newer .docx format incorporates zip compression, and text is highly compressible data.

[One exercise I require of the law students in my E-discovery class is to look at the file header of a Word .docx file to note its binary signature, PK, characteristic of a zip-compressed file and short for Phil Katz, author of the zip compression algorithm.  For grins, you can change the file extension of a .docx file to .zip and open it to see what a Word document really looks like under the hood.  Hint: it’s in XML].

John reports a similar discrepancy between new and old Excel spreadsheet formats (1,883 .xlsx files per gigabyte versus 1,307 for .xls).  Here again, the .xlsx format builds in zip compression.

But, the results are reversed when it comes to PowerPoint presentations, with John finding that there are marginally fewer of the newer .pptx files in a gigabyte (505) than the older .ppt format files (580).  This makes sense to me because Microsoft phased out the .doc format ten years ago.  Since then, presenters have gotten better about adding visual enhancements to deadly-dull PowerPoints, and they tend to add ‘fatter’ components like video clips.  The biggest factor is that pictures are highly incompressible, and common image formats (i.e., .jpg images) have always been compressed.  Compressing data that’s already compressed tends to increase, not decrease its size.

Wisely, John speaks only of document volumes and makes no effort to project page equivalencies, not even by extrapolating some postulated ‘average-pages-per-file type.’  Anything like that would be as insupportable today as it was when I wrote about it in 2007.  Also, when you look at John’s post, note that there is no data supplied concerning TIFF images.  I’m not sure why, but I can promise you this: TIFF images are MUCH fatter files, costing far more in terms of storage space and ingestion costs than their native counterparts.  Had John added TIFF to the mix, I’m confident his weighted averages would have been much different…and far less useful–much like TIFF images as a form of production. 😉

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

“Derogation of the Search for Truth”

20 Friday Dec 2013

Posted by craigball in E-Discovery

≈ 12 Comments

search for truthIn my last post, I addressed why search terms used to cull data sets in discovery should not be protected as attorney work product.  Today, I want to distinguish an attorney’s “investigative queries” (for case assessment, to hone searches or to identify privileged content) from “culling queries” (to generate data sets meeting a legal obligation, whether conceived by an attorney, client, vendor or expert).   I contend culling queries warrant no work product protection from disclosure.

Let’s assume a producing party has a sizable collection of potentially responsive electronic information.  Producing party concludes that it would be too costly, slow or unreliable to segregate the ESI by reading everything and, instead, decides to examine just those items that contain particular words or phrases.  Keyword queries thus serve to divide the ESI into two piles: one that will be reviewed by counsel and another that no one and nothing will qualitatively review.  The latter is the “discard pile.”  Culling queries may be applied iteratively, first to collect data from the enterprise and later to cull the collection for review.  The reductive process may entail the successive use of a client’s local and enterprise search capabilities and/or a law firm’s or vendor’s search tools.

The common thread is that each lexical search mechanism serves to exclude ESI lacking certain terms from substantive review.  No one ever assesses the discards for relevance or responsiveness.

Now, if we could be confident that keyword culling worked reasonably well and that the persons who came up with keywords were lexical magicians, there’d be no need to worry over the discard pile.  We could trust that what we don’t know doesn’t hurt us.

But we do know that a hefty slug of responsive items ends up in that discard pile.  We know this because studies and experience have established that keyword search is a crude, mechanical filter.  It leaves most of what we seek behind.

Whether we are leaving behind an endurable or unendurable volume of responsive items depends on just how poorly those keywords performed.  To gauge that, we’ve got to know what queries were run. Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...

Transparency of Process No Peril to Work Product

16 Monday Dec 2013

Posted by craigball in Computer Forensics, E-Discovery, Uncategorized

≈ 13 Comments

I’m rarely moved to criticize the work of other commentators because, even when I don’t share their views, I applaud the airing of the issues their efforts bring.  But sometimes a proposition is just so blatantly ill-advised, so prone to unfairly tilt the litigation playing field, that any reader and every writer should stop and say, “Wait a second….”  One such article, currently running in the New York Law Journal and called No Disclosure: Why Search Terms Are Worthy of Court’s Protection, charges that judges who require disclosure of search terms “discount or misunderstand” what the authors term the “protected nature of key aspects of the e-discovery process,” namely filtering of data by use of search terms.  The authors think that disclosure of search terms used to exclude data from disclosure compromises the work product privilege and argue that judges should “recognize that a search term is more than a collection of words, rather, the culmination of an attorney’s interaction with the facts of the case.”

Espousing the sanctity of work product privilege to an audience of litigators is like saying, “I support our troops.”  It’s mom, baseball and apple pie.  It’s also popular to paint judges as addled abusers of discretion.  But let’s not let jingoism displace judgment.  Search terms are precisely what the authors claim they are not: search terms are a collection of words.  They are lexical filters.  Nothing more.

Search terms deserve no more protection from disclosure than date ranges, file types and other mechanical means employed to exclude data from scrutiny.  Search terms strip out information that will never see the light of day nor benefit from the application of lawyer judgment as to their relevance.  In that sense, search terms are anathema to the core principles of work product and warrant more, not less, scrutiny. Continue reading →

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Print (Opens in new window) Print
  • Share on X (Opens in new window) X
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
Like Loading...
← Older posts
Newer posts →
Follow Ball in your Court on WordPress.com

Enter your email address to subscribe to this blog and receive notifications of new posts by email.

Join 2,381 other subscribers

Recent Posts

  • Fifteen Years in Your Court August 21, 2026
  • The AI Protective Order Double Standard July 27, 2026
  • Drafting RFPs for Robots to Read July 20, 2026
  • A Refresh of the Annotated ESI Protocol May 1, 2026
  • Free at Last: Ditching TurboTax for FreeTaxUSA April 5, 2026

Archives

RSS Feed RSS - Posts

CRAIGBALL.COM

Categories

EDD Blogroll

  • eDiscovery Today (Doug Austin)
  • E-Discovery Law Alert (Gibbons)
  • Minerva 26 (Kelly Twigger)
  • E-D Team (Ralph Losey)
  • Illuminating eDiscovery (Lighthouse)
  • Complex Discovery (Rob Robinson)
  • CS DISCO Blog
  • Basics of E-Discovery (Exterro)
  • Corporate E-Discovery Blog (Zapproved )
  • GLTC (Tom O'Connor)
  • The Relativity Blog
  • eDiscovery Journal (Greg Buckles)
  • Sedona Conference

Admin

  • Create account
  • Log in
  • Entries feed
  • Comments feed
  • WordPress.com

Enter your email address to follow Ball in Your Court and receive notifications of new posts by email.

Website Powered by WordPress.com.

  • Subscribe Subscribed
    Ball in your Court
    Join 2,233 other subscribers

    Have a WordPress.com account? Log in now.

  • Ball in your Court
    View site in Reader
    Manage subscriptionsSign upLog in
    Report this content
    Collapse this bar
Loading Comments...
%d